AI Blog Writer: A Problem-First Guide to Choosing and Using Blogging Software
Choosing an AI blog writer starts with identifying the publishing bottleneck and defining what a usable, trustworthy draft must achieve. The guide recommends testing shortlisted tools on the same real...
If you lead content at a B2B SaaS or professional services firm, the backlog grows while writer-hours stay fixed. Every post still has to earn the trust of a buyer who knows the subject. An ai blog writer can help you get past the blank page, but only if it reduces total production effort rather than moving the bottleneck from drafting to editing.
A polished demo rarely settles that question. Fluent sample copy does not show that a tool follows your brief, stays inside your approved sources, or reaches publish-ready content in fewer hours. Briefing, verification, editing, and publishing all still take human time. AI can handle repetitive production tasks, while strategy, claims, and final approval stay with your people.
This article gives you a problem-first process for choosing and using blogging software. We start by naming your publishing bottleneck, then separate four outcomes: drafting speed, structural fidelity, factual reliability, and editing effort. You will learn how to write acceptance criteria, which are the standards a draft must meet before your team calls it usable.
From there, we show how to test shortlisted tools on one real brief, using the same audience, approved outline, and source pack. We explain what assisted drafting does well, where unsupported generation creates risk, and who should review claims. A weighted scorecard then helps your team compare total human effort, not output volume, as a decision aid rather than a ranking.
We also cover how to tell genuinely free access from time-limited trials and paid features, using each vendor's current official terms. Detailed outline instruction sits in a separate guide, so this one stays on software evaluation. The right choice depends on your workflow, so we name no single best tool. Your editors stay in control of edits, claims, and final approval throughout. Next, we look at what an ai blog writer should solve before it drafts a single word.
What an AI blog writer should solve before it drafts
Start with your publishing bottleneck
An AI blog writer solves only the problem you point it at. Start by naming where your publishing process stalls. It might be research, outline creation, first-draft speed, revisions, approvals, or publication operations. A team waiting weeks on subject-matter review will gain little from faster drafting. A team facing the blank page every Monday may gain a lot.
Tie the tool to a real audience and business objective. One example is educating mid-market buyers before a services conversation. A general wish to use AI is too vague to test. State the improvement in practical terms. Fewer editor minutes per usable article is one example. Clearing a defined share of your backlog this quarter is another.
Measure four outcomes separately
A tool can win on one measure and lose on another, so score four outcomes on their own.
- Drafting speed: the time to a first draft, including setup and prompt preparation.
- Structural fidelity: whether the draft follows the approved outline, audience, length, and assignment requirements.
- Factual reliability: whether claims trace to supplied or independently verified sources, with no invented citations or unsupported specifics.
- Editing effort: the human minutes spent correcting, sourcing, restructuring, rewriting, and preparing the article for publication.
A draft may arrive in minutes. If it needs a full restructure and a claim-by-claim audit, it has not saved you time. It has moved the work to your editors.
Define what “usable” means to your team
Decide what “usable” means before you compare any tool. Write acceptance criteria. Cover audience fit, required sections, accurate claims, tone, and a clear next step for the reader.
Set the level of review effort your team can accept. No universal editing-time benchmark exists, so your current process is the fair baseline.
Separate failure conditions from ordinary flaws. A fabricated source or a materially unsupported claim should fail a draft outright, however well it scores elsewhere. A strong average cannot erase a false statement that carries your name. Weak transitions and a flat tone can be edited, refined, or regenerated. Invented evidence damages trust.
Test an AI blog post writer with one real brief
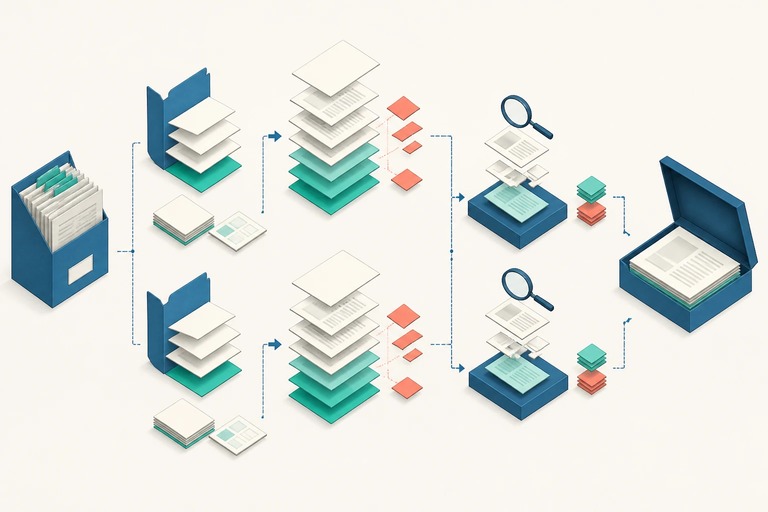
Prepare the same assignment for every tool
Choose one assignment that reflects your audience, business objective, intended reader action and format. A mid-market SaaS onboarding article that ends with a request for an implementation review works well. Give every AI blog post writer identical inputs. Those are the approved outline, the source pack, the prohibited claims and your acceptance criteria.
List each source with its title, publisher, date, relevant finding, URL and known caveats. Tell the tool to flag evidence gaps instead of filling them with guesses. If you test a free AI blog post writer, use this same single brief. That keeps the comparison fair.
Keep the outline blog post step bounded. Approve the structure first, so every tool drafts from the same outline. Our guide to outline writing covers that step in detail. Reusing one brief also shows which differences come from the tool and which come from the inputs.
Compare assisted drafting with unsupported generation
Assisted drafting helps when it works from material you supplied. It can brainstorm angles, summarize your source pack, and produce a rough draft. It can also adapt tone and list questions a person should research. That is real relief when the blank page is slowing your team.
Unsupported generation is different. Suppose you ask a tool for facts or citations without evidence. If you then treat the fluent answer as verified, the risk moves onto your editors. Fluent prose can hide a missing source.
Test source-pack-only and browsing-enabled workflows separately if both matter to you. Source-pack-only runs show how well a tool respects your evidence. Browsing runs show what it adds and what it invents. Record the model, settings, features and date for each run. Where practical, repeat generations and have reviewers score drafts without seeing the tool name. Blind scoring keeps a polished demonstration from outweighing the evidence in front of you.
Keep human review explicit
Name one person who validates statistics, quotations, dates and product capabilities against primary or approved sources. This person should be able to say yes or no to each claim after checking it. Name a second person who approves originality, usefulness, privacy considerations and publication readiness. Your team keeps editorial responsibility and control of edits, refinements and regeneration.
Log reviewer and editor minutes separately for factual correction, structural changes, style edits and sourcing. Those four buckets show where a tool costs you time.
Published evidence supports running a pilot. Noy and Zhang (2023) studied 453 professionals on writing tasks. They found that ChatGPT access cut task time by 40% and raised measured quality by 18%. Those were bounded tasks and did not cover a full B2B publishing pipeline. Take the result as a reason to test. Let your own logged minutes decide.
Choose the best AI for writing blogs with a weighted scorecard
Use a weighted scorecard as team decision support
The best AI for writing blogs fits your brief, your risk tolerance and your workflow. No single tool wins for every team. A scorecard makes that fit visible. The weights below are illustrative, so adjust them to your own bottleneck.
| Criterion | Illustrative weight | Rating question |
|---|---|---|
| Brief adherence | 30% | Did the draft meet audience, objective, format and prohibited-claim rules? |
| Evidence handling | 25% | Did it use the source pack faithfully and flag gaps? |
| Editing effort | 25% | How much human time did it take to reach the acceptance criteria? |
| Access/cost fit | 20% | Does the tested plan meet access, privacy, export and budget needs? |
Rate every criterion on the same anchored 1 to 5 scale. Write down the reason for each score. Keep critical failures, such as fabricated citations, as pass/fail gates. The weighted total reflects your priorities and test conditions. It is no industry ranking and no ranking guarantee.
Compare total effort, not just output volume
Log time for each tested workflow in five parts: brief preparation, generation, editing, verification and approval. Compare the total human effort needed to reach the same acceptance criteria. Words generated and subscription price each show only part of the cost.
Consider a hypothetical example. Tool A has a $10 per-article subscription allocation. It needs 75 minutes of combined review and correction at $60 an hour. That brings its cost to $85 per article. A free plan needs 115 minutes of the same work, so it costs $115. The cheaper plan becomes the more expensive workflow. These inputs are invented for illustration, and your own logs should replace them.
Tool choice alone does not guarantee rankings, traffic, lead quality or conversions.
Make the comparison useful for different stakeholders
Each reader of your results asks a different question. Content leads want brief adherence and manageable editing. Directors want productivity and cost. Editors want evidence they can trace and control over revisions. Procurement and privacy reviewers ask about data use, retention, security, exports and contract terms.
Record the same compact list for every shortlisted tool:
- Plan and model tested: the exact plan, model and date
- Source handling: how it treated the supplied source pack and flagged gaps
- Reviewer tasks: what a person still had to validate
- Editor minutes: time for structure, style, facts and sourcing
- Access limits: quotas, trial length, seats and export options
- Price-check date: when you verified the price, currency and billing cycle
One list per tool lets each stakeholder find an answer without a separate report.
Verify access, protect editorial ownership, and route the next step
Distinguish free access from trials and paid features
A free blog writer AI can mean four different things. It may be an ongoing free tier or a time-limited trial. It may also be a limited credit allowance or a paid feature preview. Label the access type before you test. Check the vendor's official pricing and plan pages. Look for quotas, payment details, renewal and cancellation, commercial-use terms, seats, exports, and regional limits. Read the data-use, retention, model-training, and deletion terms before you enter sensitive or proprietary material. Date-stamp every price and access detail you record. If you can confirm a claim only from an old comparison or memory, leave it out.
Keep this page focused on tool evaluation
This guide covers how to choose an AI blog writer, including the best and free options. Detailed outline instruction lives elsewhere. A fair software test needs a prepared structure. Read "Blog Outline: A Reusable Template for Clear, Purposeful AI-Assisted Content." It helps you build the approved outline every tool should follow. After your tests, continue with "SEO Blog Writing Tool: Evaluate Quality Controls from Outline to Publication." That guide covers SEO controls and publication governance.
Move from shortlist to a controlled decision
Narrow your shortlist to two tools. Run both on the same brief, with the same scorecard and acceptance criteria, before you change your workflow. Let the decision reflect measured effort, evidence handling, access fit, and the human review each draft needs. Output volume and a polished demo should not decide it.
Bring your results to us. An implementation review helps you apply this method to your own workflow. It shows where AI assistance can ease your editorial bottleneck. Your editors stay in control of edits, claims, and final approval throughout.
Choose an AI Blog Writer With Confidence
The blank page is only one part of your publishing bottleneck. The tool worth keeping is the one that gives your editors time back, and your logged minutes will show that more honestly than any demo. Treat every score as evidence about your brief, your sources, and your reviewers, not as a verdict on the whole market.
The scorecard supports your team's judgment. It does not name a universal winner, and it cannot predict search performance. Fabricated citations and unsupported claims stay as pass/fail gates, so a high total never excuses them. With named reviewers owning claims and publication approval, your people stay in control of every edit, refinement, and regeneration.
Your next step is concrete. Pick the two tools on your shortlist, run both on the same brief with the same approved outline, source pack, acceptance criteria, and scorecard, and log minutes for brief preparation, generation, editing, verification, and approval. Then request an implementation review of those results before you change your workflow. We will help you see where AI assistance can ease your editorial bottleneck and where human review should remain.
If your structure is not ready for a fair test, start with Blog Outline: A Reusable Template for Clear, Purposeful AI-Assisted Content, then return to run your comparison.